Friday, March 28, 2014

RabbitMQ, .NET and SSL: easier said than done

So we are currently implementing a RabbitMQ cluster to be part of our infrastructure and we will be communicating with this cluster through .NET clients using the standard RabbitMQ Client for .NET.
Everything worked just fine until we wanted to use SSL on those connections. Then everything went to hell.

So first the specifics of how we connect. We simply use an AMQP connection string to connect. Setting the Uri property in the ConnectionFactory class:

var cf = new ConnectionFactory();
cf.uri = new Uri("amqp://user:pass@172.20.0.72:5671/vhost");
var connection = cf.CreateConnection();

So first I simply set the Ssl.Enable property in the ConnectionFactory to true:

var cf = new ConnectionFactory();
cf.Ssl.Enabled = true;
cf.uri = new Uri("amqp://user:pass@172.20.0.72:5671/vhost");
var connection = cf.CreateConnection();

But it wasn't that simple. This gave me a BrokerUnreachableException with the message "None of the specified endpoints were reachable". The inner exception was an IOException with the message "Authentication failed because the remote party has closed the transport stream.". Followed by long stack-trace ending at: System.Net.Security.SslState.StartReadFrame(Byte[] buffer, Int32 readBytes, AsyncProtocolRequest asyncRequest).

So then I simply followed the instructions presented at the RabbitMQ pages (http://www.rabbitmq.com/ssl.html). I imported the root certificate, added the client certificate to the program and tried again:

var cf = new ConnectionFactory();
cf.Ssl.Enabled = true;
cf.Ssl.ServerName = "clienthost";
cf.Ssl.CertPath = @"C:\client-certs\keycert.p12";
cf.Ssl.CertPassphrase = "password";
cf.uri = new Uri("amqp://user:pass@172.20.0.72:5671/vhost");
var connection = cf.CreateConnection();

Same error as before, but now the inner exception has the message: "connection.start was never received, likely due to a network timeout."
Then I noticed something somewhere (can't remember where, probably in one of the RabbitMQ documents) about AMQPS. Sounds reasonable. HTTP -> HTTPS, so AMQP -> AMQPS:

var cf = new ConnectionFactory();
cf.Ssl.Enabled = true;
cf.Ssl.ServerName = "clienthost";
cf.Ssl.CertPath = @"C:\client-certs\keycert.p12";
cf.Ssl.CertPassphrase = "password";
cf.uri = new Uri("amqps://user:pass@172.20.0.72:5671/vhost");
var connection = cf.CreateConnection();

Queue Dennis Nedry....
Then I spend literally three hours of googling trying to find answers, but not one helped. I finally downloaded the source code for the RabbitMQ client (thank god for open source) and stepped through the connection process. That's where I noticed something funny. During the connect, the SSL options appeared to have disappeared. That's when I got an awful realization:

var cf = new ConnectionFactory();
cf.uri = new Uri("amqps://user:pass@172.20.0.72:5671/vhost");
cf.Ssl.Enabled = true;
cf.Ssl.ServerName = "clienthost";
cf.Ssl.CertPath = @"C:\client-certs\keycert.p12";
cf.Ssl.CertPassphrase = "password";
cf.uri = new Uri("amqps://user:pass@172.20.0.72:5671/vhost");
var connection = cf.CreateConnection();

...and it works. Are you effing kidding me?!
Setting the Uri property resets the SSL properties. Even though you cannot specify the SSL properties thought the connection string. So there is no reason for it to be reset like that.
If you take change the connection string back to "amqp://" you will get an exception ("The remote certificate is invalid according to the validation procedure."); even if you set the SSL Enabled property after.

So I hope this will save you a few hours of frustration. Right now I'm just happy I got it to work.

UPDATE: It can even be easier!

Wednesday, May 19, 2010

Even more Facebook privacy

I have a Facebook account. I primarily use it to share funny photo’s and funny links with friends. To me it’s the e-mail of the new millennium.
But lately you read a lot of criticism about Facebook’s privacy policy. A nice ‘evolution’ of Facebook’s privacy settings can be found here. It shows how settings are getting less private with each new Facebook update. Then there is also the Facebook privacy scanner. I highly recommend everyone giving that thing a try to see where the weak spots are in your Facebook privacy settings.

But there is more. It’s not just what people can find out about you when they look you up on Facebook. You should also be concerned about what a website can find out about you when you visit them. Remember the fiasco that was Facebook Beacon? Well, there still is something similar I think. The web sites aren’t allowed to post to your news feed, but they might be able to gather information about you.

When I recently reviewed my privacy settings, I went to the page where you can see which Facebook applications have which rights. And to my surprise I even saw a few websites I visited recently in that list. I didn’t recall giving them access to my Facebook profile, but there they were. This looks a lot like the “Instant personalisation pilot programme” I also saw in the privacy options. But I have that option turned off.

But I found a way to ensure no web site will ever know I’m logged into Facebook. You see, modern browsers offer this extra sandbox for browsing. I use Google Chrome primarily and it offers the “Incognito” option. Internet Explorer offers something similar with “InPrivate Browsing”. I haven’t tested it with Internet Explorer, but when I open Facebook in an “Incognito” window in Google Chrome, that Facebook session is limited to that browser window. I then use another Google Chrome browser window (a non-“Incognito” window) for my normal browsing. That way, when I visit a web site, it’ll never know I am currently logged into Facebook and I have extra privacy.

Wednesday, March 17, 2010

My WCF service doesn’t generate a WSDL!

Recently I added a new WCF web service to an pre-existing application. That application already contained two other WCF web services and was specifically partitioned in that it had the interfaces, data classes and SVC files in separate projects. So I just copied the necessary files from inside the projects and adjusted them to suit my needs, adding many new data classes for the new interface.
I compiled to make sure I didn’t have any syntax errors and then I copied and changed the WCF config parts in the web.config.

So far so good. The code compiled and I could access the SVC page from my browser.
I then started SOAPUI so I could test the web service and pointed it towards the WSDL interface of the new web service. Imagine my surprise when it did find the web service, but not a single method from it.
I checked the WSDL from my browser and lo’-and-behold: There were only endpoints in there. No methods and data structures.

I re-checked the WSDL, comparing it to another, working, web service we had and it was all correct. Then I went over the SVC, service contract interface and implementation again and I noticed a line similar to this:

[OperationContract(Action="http://my-namespace.com/app/1.0/DoStuff", ReplyAction="*")]
void DoStuff();

I didn’t know what that “ReplyAction” was about, but that wildcard doesn’t seem right to me. I checked the interface I copied it from and that interface was an older, pre-existing SOAP web service that we added to our app by using the svcutil.exe tool. So that “ReplyAction” was added by that tool.
It turns out that ReplyAction"=”*” means: don’t use a SOAP action in the reply. This has to do with a WCF web service that is building the messages by itself, instead of letting the framework do it for you. This was probably caused by the old web service that didn’t quite fit into the mold WCF has created for us to develop web services in. But since WCF needs to provide us with the ability to create all kinds of web services that are legal according to the SOAP standards, it provides the ability to create the SOAP messages by hand. So when we used the WCF svcutil.exe tool, it determined that it needed to do that for that particular web service. Then when I copied those files for my new web service, I got stuck with the “ReplyAction”.

I removed the “ReplyAction” from the “OperationContract” and after that the web service auto-generated a WSDL just fine.

Saturday, December 5, 2009

DataAnnotations in ASP.NET MVC2 without Dynamic Data

The last few days I’ve been playing with VS2010 beta 2 and ASP.NET MVC2. I hadn’t done that much with the first version of ASP.NET MVC, but I hope to get some more time to play with version 2.

After seeing how easy validation of data input can be in the PDC video on ASP.NET MVC2 from Scott Hanselman, I wanted to try it out for myself. I had already started working on an MVC2 project and it used manual validation. So I added the data annotation attributes on the class and….it didn’t work… Turns out that the thing that transforms the HTTP form data into a .NET object, the Model Binder, needs to support it and the default binder is very simple and does not support it. If you talk to a database with the Dynamic Data Framework somewhere along the line a model binder is used that does support it and apparently Scott used dynamic data in his demo.

The project I had started was using the ADO.NET Entity Framework which does not have support for data annotations (yet) and I didn’t feel like switching to the Dynamic Data Framework just for the validation. But then it turns out you can easily(?) write your own binder and make it support the data annotation attributes. Or rather, extend the default binder. I found this at a blog post by Brad Wilson about using data annotations in ASP.NET MVC and it even pointed me to the sample project he talked about in his blog post. I downloaded it and tried to build it as a .NET 4.0 project, but since the sample was written for MVC1 and .NET 3.5SP1 I got compiler errors about missing functions at first and when I got it to compile I got a nasty runtime error:

This property setter is obsolete, because its value is derived from ModelMetadata.Model now.

The compiler errors about the missing function took some reasoning, but you need the change this code which appears in two places and is slightly different in the second place:

if (!attribute.TryValidate(bindingContext.Model, validationContext, out validationResult))
{
   bindingContext.ModelState.AddModelError(bindingContext.ModelName, validationResult.ErrorMessage);
}

Into this:

validationResult = attribute.GetValidationResult(bindingContext.Model, validationContext);
if(validationResult != ValidationResult.Success)
{
   bindingContext.ModelState.AddModelError(bindingContext.ModelName, validationResult.ErrorMessage);
}

After some searching for the runtime error I found an answer on StackOverflow. The code discussed in that article is a little different then the code in the binder sample I am using, but it was enough for me to get it to work. Basically you need to change this:

var innerContext = new ModelBindingContext()
{
   Model = propertyDescriptor.GetValue(bindingContext.Model),
   ModelName = fullPropertyKey,
   ModelState = bindingContext.ModelState,
   ModelType = propertyDescriptor.PropertyType,
   ValueProvider = bindingContext.ValueProvider
};

Into this:

var innerContext = new ModelBindingContext()
{
   ModelMetadata = ModelMetadataProviders.Current.GetMetadataForType(() => bindingContext.Model, propertyDescriptor.PropertyType),
   ModelName = fullPropertyKey,
   ModelState = bindingContext.ModelState,
   ValueProvider = bindingContext.ValueProvider
};

And it will work.

Next was finding out how to use it exactly. The blog post about the sample binder would receive the entire model when the function is called on the controller, but my code only received an identifier and I need to get the rest of the data out of the database. So just using “ModelState.IsValid” wasn’t enough in my case. I also needed to call “UpdateModel” to have the binder transform the input data in the .NET object that I use in my code. The problem I ran into there was that upon updating the model, the validation rules would also run and an exception would be thrown when the validation failed. This code gives me the exception:

[AcceptVerbs(HttpVerbs.Post)]
public ActionResult Edit(string lastName, FormCollection collection)
{
   Person person = new Person();
   UpdateModel(person);
   PersonController.personStore[lastName] = person;

   return RedirectToAction("Details", person);
}

It turns out I should not be using UpdateModel, but rather TryUpdateModel. That allows me to update the model and the validation to fail without resorting to exception handling. Like so:

[AcceptVerbs(HttpVerbs.Post)]
public ActionResult Edit(string lastName, FormCollection collection)
{
   Person person = new Person();
   bool isModelValid = TryUpdateModel(person);
   if(isModelValid == true)
   {
       PersonController.personStore[lastName] = person;

       return RedirectToAction("Details", person);
   }
   else
   {
       person.LastName = lastName;
       return View(person);
   }
}

Doing it like that gives me the nice error message I was looking for:

nice-error

Thursday, July 23, 2009

Windows Workflows that restart themselves?

A few weeks ago I got assigned a fun bug. We have a WF-based order system and it seems that occasionally orders that had been send earlier would start all over by themselves.
And sure enough, when looking at the logging I saw that the order would start over. So how did this happen?

First off I noticed it only happened with orders that required a callback in their process. So orders that, at one point or another, would be idle and waiting for an external event. All other orders never gave a problem.
Then I also noticed that the orders restarted themselves after the system itself had been idle for around 30 minutes.
So workflows that were idle were restarting after 30 minutes of system inactivity. They were re-processed when a new order was sent (you'd then see a whole slew of old orders restarting).

Whenever something happens on IIS after around 30 minuted of inactivity I assume it's always related to the fact that after 20 minutes of inactivity (by default) IIS will stop the web service/application to spare resources. The next request that comes in will cause IIS to startup the web service/application again. So it's pretty much safe to assume the problem is related to the web service stopping and restarting.

So why would an order start all over again, after the web service is being restarted. The most likely reason would be that the Workflow Runtime was unable to save its state. So without knowing where the workflow left off, but knowing that the worklfow does exist, it seems logical the workflow would just restart.

We checked the config and it did have the WorkflowPersistenceService configured and loaded. However, it's "UnloadOnIdle" setting was missing. Meaning it defaults to false. Meaning workflows don't unload when they are idle. And more importantly: a workflow is only persisted when you explicitly tell it to, or when it is unloaded.
Since neither happened on our system the workflows never stored their state and restarted when the web service restarted.

Of course this was not figured out that quickly. I assumed the operational engineers would use the configuration we'd send them, so I never bothered to check it. If I had, I would have solved this bug in a matter of minutes. Now it took us days of prodding, testing and praying. Until another developer mentioned he had noticed the config looked almost the same, but not quite the same. *sigh*.
Bugtracking rule #1: Always check the config!

Saturday, June 13, 2009

EU wants other browsers in Windows

The European Union is working on a anti-trust case against Microsoft. They claim that the consumer (of the Windows operating system) has no choice in its browser and only has Internet Explorer because it is bundled with Windows. The EU wants Microsoft to start bundling other browsers (Safari, Opera, Firefox, Chrome) to give the user more choices.

I find that an absurdly stupid idea. I can understand that they would want to give people a choice. but let’s face it, most computer users are morons when it comes to computers (no offence). They don’t know anything about computers. Hell, they never updated their software until Microsoft set the default to “don’t ask, just update”. And know they should need to choose between difference web browser? That’s a recipe for disaster.

Aside from users not knowing that they want or need, there are also business issues to consider. Let’s say you buy Windows and you choose to install Safari. And now when you visit your favourite web site, Safari crashes every time. Who will you call for support? Well, Microsoft of course. It’s their Windows system you bought and Safari was included with that. So now all of a sudden Microsoft has to offer support for Safari, or Opera, or Firefox, etc.

Also, now it appears there is a major security issue with Opera, which you installed because it came with Windows. Who is going to fix that? Not Microsoft, because they don’t make that product. Who are you demanding should fix it? Well, Microsoft of course. Because it came with their Windows system did it not? Can Microsoft guarantee that Opera follows its security guidelines and makes the software as safe as possible?

Suppose there was a security issue and Opera fixed it. How are you going to get the security fix? I highly doubt its going to be through Microsoft Update. So the update will probably not be installed automatically by default. And every browser will have its own system for updates.

Microsoft also has strict guidelines on how programs look and work. Safari is made by Apple. In all honesty I’ve never used Safari for Windows, but I assume it will look strikingly similar to Safari for Mac OS. I do use iTunes and it looks nothing like a Windows application, because it’s made for a completely different OS. Apple has it’s own user interface guidelines and they are a lot different from the Microsoft guidelines. So now you have out-of-the-box software that looks (and behaves) completely different than all the other software that is installed.

So, yeah, I’m not much for bundling different browser with Windows. I would love to present people a choice, but Windows should stick with Internet Explorer. Why not, upon first connection with internet, give people a page that tells them they have a choice in browsers and give them links to different websites for those browsers. But bundling software made by completely different companies with Windows is a stupid idea.

And just so you know: I’m a Firefox user and only use Internet Explorer at work, because our intranet doesn’t work correctly with Firefox.

PS
This is not my original idea, I read it somewhere else, but why give people only the choice between Internet Explorer, Firefox, Safari, Opera and Chrome? Why not all of the gazillion different web browsers that are out there? Doesn’t seem fair to the little guy. On the other hand Opera is pretty much “the little guy” and since they are furiously trying to get their browser bundled with Windows I really doubt they’re in it for “what’s good for the customer”. As I see it, they just use this to try and increase their market share.

Friday, February 20, 2009

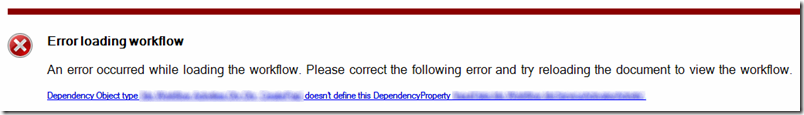
Error loading workflow

Have you ever seen an error message like this when developing a Windows Workflow application?

ErrorLoadingWorkflow

I have. Lots of times.

I’m not sure what is causing this. We have a project that contains the workflow and we have several other projects that contain the activities we use. Also we do a little inheritance, where all workflow inherit from a base workflow and all activities inherit from a base activity. The only thing they inherit are properties and functions. We do not have a basic workflow with activities which other workflow then add to. Although I would really love to have that!

So far I discovered two possible solutions workarounds:

  1. Rebuild the projects containing the workflow classes.
  2. Restart Visual Studio.

Solution #1 is preferable, because otherwise, if you have a large solution, the time it takes for Visual Studio to load your solution can get really annoying. So what I did was create a simple small MSBuild script that cleans and then builds all my workflow project. It starts by cleaning the projects and then builds the projects. First building the projects containing the activities and then the projects containing the workflows. Most of the time that worked for me. And you don’t even need to close anything. You can even keep the workflow designer open with the error message showing. After the build it will refresh and if successful the workflow will be shown.

But sometimes that does not work. Then I would have to quit Visual Studio, run my build script and open Visual Studio again.

It’s also very possible that you have a genuine problem or bug. It is pretty easy to create a situation where you end up being unable to open the workflow in the workflow designer and you’ll have to edit the code-behind file by hand.

Now I’m sure that our inheritance aggravates some of the problems as inheritance isn’t officially supported in Windows Workflow (although I heard they might have something for that in WF 4.0, but I haven’t checked that out yet), but I suspect you’ll run into these problems every now and then even if you do not use inheritance.